Peking University · robot AI model
ViGAR
China · 2026
Sources retrieved: 19 November 2026 (A, B, C)
- Model type
- World action modelSource and note: Model typeA arxiv.org/abs/2610.02368 · Retrieved 19 November 2026Note. “We propose Visual Goal-conditioned Action Reasoning (ViGAR), a hierarchical framework that factorizes manipulation into a visual subgoal planner and a subgoal executor.” Hugging Face teaser describes “a subgoal planner and a world-action policy”.
- What it controls
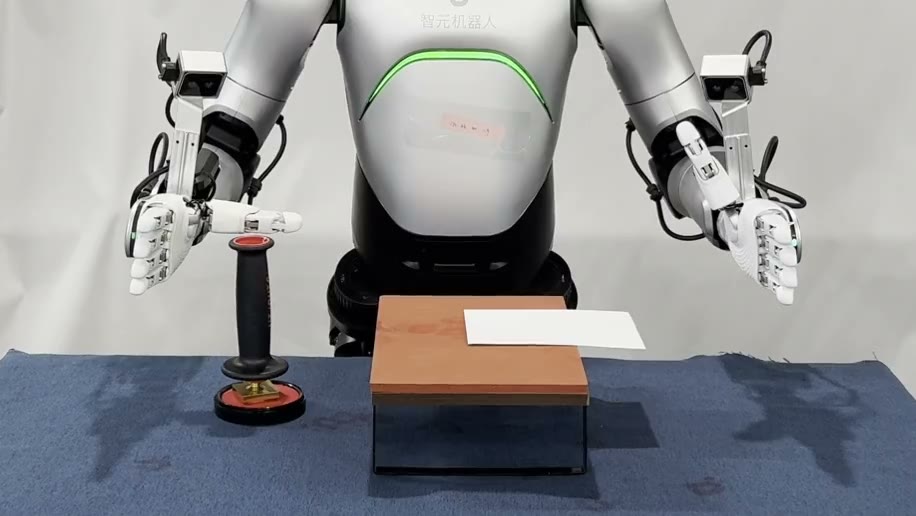
- Arms and handsSource and note: What it controlsB dagroup-pku.github.io/ViGAR/ · Retrieved 19 November 2026Note. “Experiments run on an AgiBot A2 with two 7-DoF arms, two wrist cameras and one front-facing camera.”
- Inputs
- Camera LanguageSource and note: InputsA arxiv.org/abs/2610.02368 · Retrieved 19 November 2026Note. “Given the current observation and global instruction, the subgoal planner predicts a visual subgoal for the next subtask.”
- Access
- Open weights (download)Source and note: AccessC huggingface.co/DAGroup-PKU/ViGAR · Retrieved 19 November 2026Note. “Evaluation code and checkpoints on **RoboTwin**.”
- Base model
- Cosmos3-NanoSource and note: Base modelB dagroup-pku.github.io/ViGAR/ · Retrieved 19 November 2026Note. “Both share the Cosmos3-Nano reasoner–generator backbone.”
- Licence document
- OpenMDW-1.1Source and note: Licence documentC huggingface.co/DAGroup-PKU/ViGAR · Retrieved 19 November 2026Note. Hugging Face model card header: “license_name: openmdw-1.1”. License section: “Original project code uses the [MIT license](https://github.com/DAGroup-PKU/ViGAR/blob/main/LICENSE). Bundled components retain their upstream licenses. Cosmos-derived model materials use OpenMDW-1.1.”
Specifications
7 of 14 stated 7 not stated
5 fields hidden 2 not-stated fields with a note stay ·
How to read the figuresShow guideClose
- not statedNo source
- 0Reported as zero
- ASource
Select a source marker for source details and notes.
Release1/1 disclosed
Released1 October 2026
Source and note: ReleasedA arxiv.org/abs/2610.02368 · Retrieved 19 November 2026Note. arXiv submission date: “Submitted on 1 Oct 2026”.
Input and output3/4 disclosed
Model typeWorld action model
Source and note: Model typeA arxiv.org/abs/2610.02368 · Retrieved 19 November 2026Note. “We propose Visual Goal-conditioned Action Reasoning (ViGAR), a hierarchical framework that factorizes manipulation into a visual subgoal planner and a subgoal executor.” Hugging Face teaser describes “a subgoal planner and a world-action policy”.
InputsCamera Language
Source and note: InputsA arxiv.org/abs/2610.02368 · Retrieved 19 November 2026Note. “Given the current observation and global instruction, the subgoal planner predicts a visual subgoal for the next subtask.”
What it controlsArms and hands
Source and note: What it controlsB dagroup-pku.github.io/ViGAR/ · Retrieved 19 November 2026Note. “Experiments run on an AgiBot A2 with two 7-DoF arms, two wrist cameras and one front-facing camera.”
Degrees of freedom controlledNot stated
Size and speed0/2 disclosed
ParametersNot stated
Control rateNot stated
Where it runs and what it is built on1/2 disclosed
On robot or cloudNot stated
Base modelCosmos3-Nano
Source and note: Base modelB dagroup-pku.github.io/ViGAR/ · Retrieved 19 November 2026Note. “Both share the Cosmos3-Nano reasoner–generator backbone.”
Openness2/3 disclosed
AccessOpen weights (download)
Source and note: AccessC huggingface.co/DAGroup-PKU/ViGAR · Retrieved 19 November 2026Note. “Evaluation code and checkpoints on **RoboTwin**.”
Licence documentOpenMDW-1.1
Source and note: Licence documentC huggingface.co/DAGroup-PKU/ViGAR · Retrieved 19 November 2026Note. Hugging Face model card header: “license_name: openmdw-1.1”. License section: “Original project code uses the [MIT license](https://github.com/DAGroup-PKU/ViGAR/blob/main/LICENSE). Bundled components retain their upstream licenses. Cosmos-derived model materials use OpenMDW-1.1.”
Licence typeNot stated
The developer’s own claims0/2 disclosed
Learns new tasksNot stated
Source and note: Learns new tasksA arxiv.org/abs/2610.02368 · Retrieved 19 November 2026Note. “using a global goal image as context can induce different subtask decompositions and behaviors without parameter updates.”
Works across robotsNot stated
Source and note: Works across robotsYes only if the developer itself says the model runs on different robot models, for example robots from two manufacturers or two of one manufacturer’s models. Several units of the same robot do not count.
Notes
Developed by researchers from Peking University, AgiBot, and CocoMatrix.
Described by the authors as “We propose Visual Goal-conditioned Action Reasoning (ViGAR), a hierarchical framework that factorizes manipulation into a visual subgoal planner and a subgoal executor.”
Sources
One line per source, not per figure: a source has one retrieval date.
- Aarxiv.org/abs/2610.02368Retrieved 19 November 2026
- Bdagroup-pku.github.io/ViGAR/Main source. Retrieved 19 November 2026
- Chuggingface.co/DAGroup-PKU/ViGARRetrieved 19 November 2026
More models
Same developer
LAWPeking University
- No photograph
LDA-1BPeking University
- No photograph
MM-NavPeking University
- No photograph
TrackVLAPeking University
- No photograph
TrackVLA++Peking University
Uni-NaVidPeking University