JD · robot AI model
JoyAI-RA 0.1
China · 2026
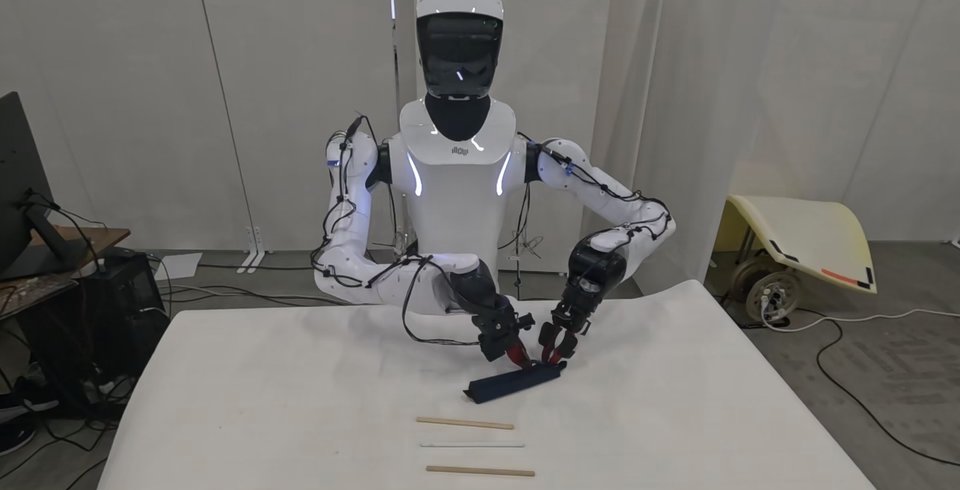
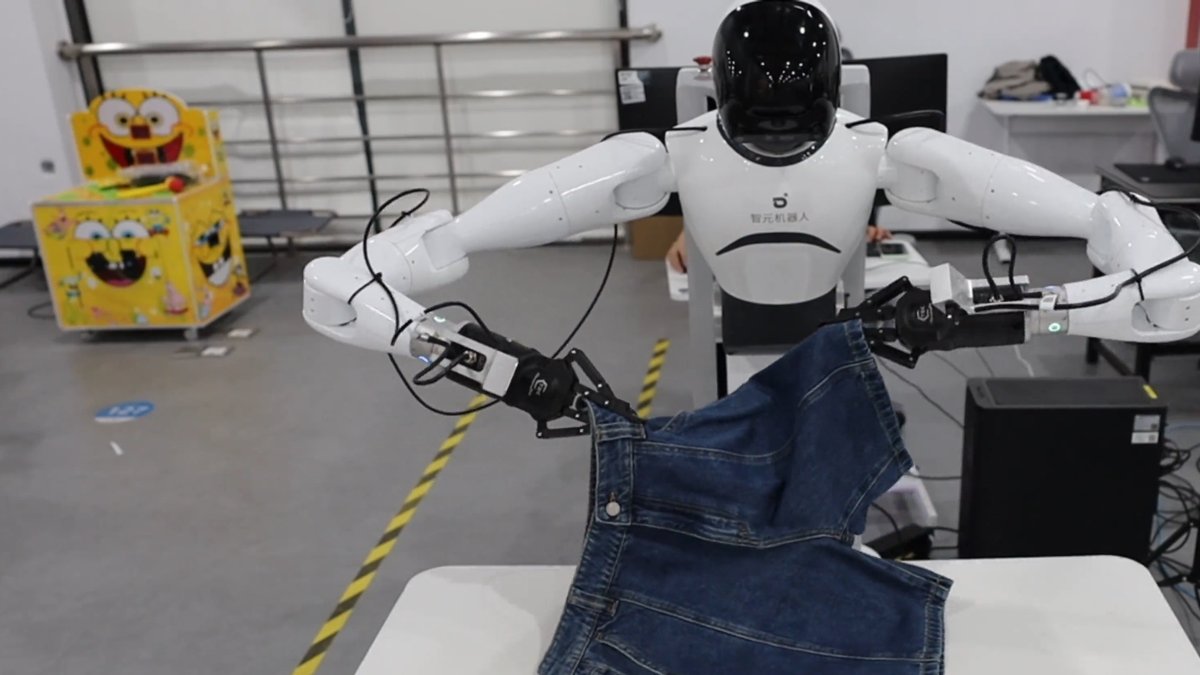
Runs on G1 by AgibotSource and note: G1A arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026
Sources retrieved: 10 November 2026 (A, B)
- Model type
- Vision-language-action (VLA)Source and note: Model typeB arxiv.org/abs/2604.20100 · Retrieved 10 November 2026Note. arXiv abstract: JD describes the model as “a vision-language-action (VLA) embodied foundation model tailored for generalizable robotic manipulation”.
- What it controls
- Arms and handsSource and note: What it controlsA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. Normalised from JD wording: the unified action vector covers all actuator groups, “including the left and right arms, the left and right dexterous hands, and the left and right grippers”. The paper also says “JoyAI-RA predicts temporally consistent action sequences for downstream control”.
- Inputs
- Camera Language Robot stateSource and note: InputsA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. Normalised from JD wording: “Given multimodal inputs consisting of language instructions, visual observations, and proprioceptive states”.
Specifications
6 of 14 stated 8 not stated
6 fields hidden 2 not-stated fields with a note stay ·
How to read the figuresShow guideClose
- not statedNo source
- yesStated by a source
- 0Reported as zero
- ASource
Select a source marker for source details and notes.
Release1/1 disclosed
Released22 April 2026
Source and note: ReleasedB arxiv.org/abs/2604.20100 · Retrieved 10 November 2026Note. [A] arXiv abstract page: “Submitted on 22 Apr 2026” (v1).
Input and output3/4 disclosed
Model typeVision-language-action (VLA)
Source and note: Model typeB arxiv.org/abs/2604.20100 · Retrieved 10 November 2026Note. arXiv abstract: JD describes the model as “a vision-language-action (VLA) embodied foundation model tailored for generalizable robotic manipulation”.
InputsCamera Language Robot state
Source and note: InputsA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. Normalised from JD wording: “Given multimodal inputs consisting of language instructions, visual observations, and proprioceptive states”.
What it controlsArms and hands
Source and note: What it controlsA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. Normalised from JD wording: the unified action vector covers all actuator groups, “including the left and right arms, the left and right dexterous hands, and the left and right grippers”. The paper also says “JoyAI-RA predicts temporally consistent action sequences for downstream control”.
Degrees of freedom controlledNot stated
Source and note: Degrees of freedom controlledA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. JD describes a fixed-length unified action vector, not a number of controlled joints: “unified-vector dimensions without a corresponding realized degree of freedom are masked in the loss”.
Size and speed0/2 disclosed
ParametersNot stated
Control rateNot stated
Where it runs and what it is built on0/2 disclosed
On robot or cloudNot stated
Base modelNot stated
Source and note: Base modelA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. JD describes the language-vision part only as “a vision-language model (VLM) handles vision-language understanding” and does not name it.
Openness0/3 disclosed
AccessNot stated
Licence documentNot stated
Licence typeNot stated
The developer’s own claims2/2 disclosed
Learns new tasksNeeds retraining
Source and note: Learns new tasksA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. Developer claim. Paper, post-training on the target robot: “In the post-training stage, only data collected from the target robot embodiment is used”. “During post-training, all model parameters are updated end-to-end”.
Works across robotsYes
Source and note: Works across robotsA arxiv.org/pdf/2604.20100 · Retrieved 10 November 2026Note. Developer claim: the framework “equips JoyAI-RA to scale across heterogeneous data sources and generalize to diverse tasks and robot embodiments”. The paper evaluates it in simulation on RoboTwin 2.0 and RoboCasa GR1 Tabletop tasks and on a real AgiBot G1.Yes only if the developer itself says the model runs on different robot models, for example robots from two manufacturers or two of one manufacturer’s models. Several units of the same robot do not count.
Notes
JD Joy Future Academy describes JoyAI-RA 0.1 in its arXiv paper as “a vision-language-action (VLA) embodied foundation model tailored for generalizable robotic manipulation”.
The paper reports real-robot tests on one robot: “we conduct Real-World Agibot Benchmark on the AgiBot G1 humanoid robot platform”.
Sources
One line per source, not per figure: a source has one retrieval date.
- Aarxiv.org/pdf/2604.20100Main source. Retrieved 10 November 2026
- Barxiv.org/abs/2604.20100Retrieved 10 November 2026