Scale AI & Hugging Face LeRobot · robot AI model
FineART-VLA
United States · 2026
Sources retrieved: 19 November 2026 (A, B, C)
- Model type
- Vision-language-action (VLA)Source and note: Model typeB arxiv.org/abs/2609.36416 · Retrieved 19 November 2026Note. Paper: “We also introduce FineART-VLA, a vision-language- action policy that predicts its own next subtask to guide its actions.”
- What it controls
- Arms and handsSource and note: What it controlsA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Model card: “14 joint and gripper dimensions; absolute action targets”
- Inputs
- Camera Language Robot stateSource and note: InputsA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Model card: “Camera views + subtask + robot state → continuous action chunk”
- Access
- Open weights (download)Source and note: AccessB arxiv.org/abs/2609.36416 · Retrieved 19 November 2026Note. Paper: “We open-source the full dataset, model weights, and training code.”
- Base model
- π₀.₅Source and note: Base modelA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Model card: “building on Physical Intelligence's π₀.₅”.
- Licence document
- GemmaSource and note: Licence documentA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. “The checkpoint retains the **Gemma license** inherited through its PaliGemma/π₀.₅ initialization.” “The LeRobot implementation is available under Apache 2.0”
Specifications
10 of 14 stated 4 not stated
2 fields hidden 2 not-stated fields with a note stay ·
How to read the figuresShow guideClose
- not statedNo source
- yesStated by a source
- 0Reported as zero
- ASource
Select a source marker for source details and notes.
Release1/1 disclosed
Released29 September 2026
Source and note: ReleasedC arxiv.org/abs/2609.36416v1 · Retrieved 19 November 2026Note. arXiv v1: “Submitted on 29 Sep 2026”.
Input and output4/4 disclosed
Model typeVision-language-action (VLA)
Source and note: Model typeB arxiv.org/abs/2609.36416 · Retrieved 19 November 2026Note. Paper: “We also introduce FineART-VLA, a vision-language-
action policy that predicts its own next subtask to guide its actions.”
InputsCamera Language Robot state
Source and note: InputsA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Model card: “Camera views + subtask + robot state → continuous action chunk”
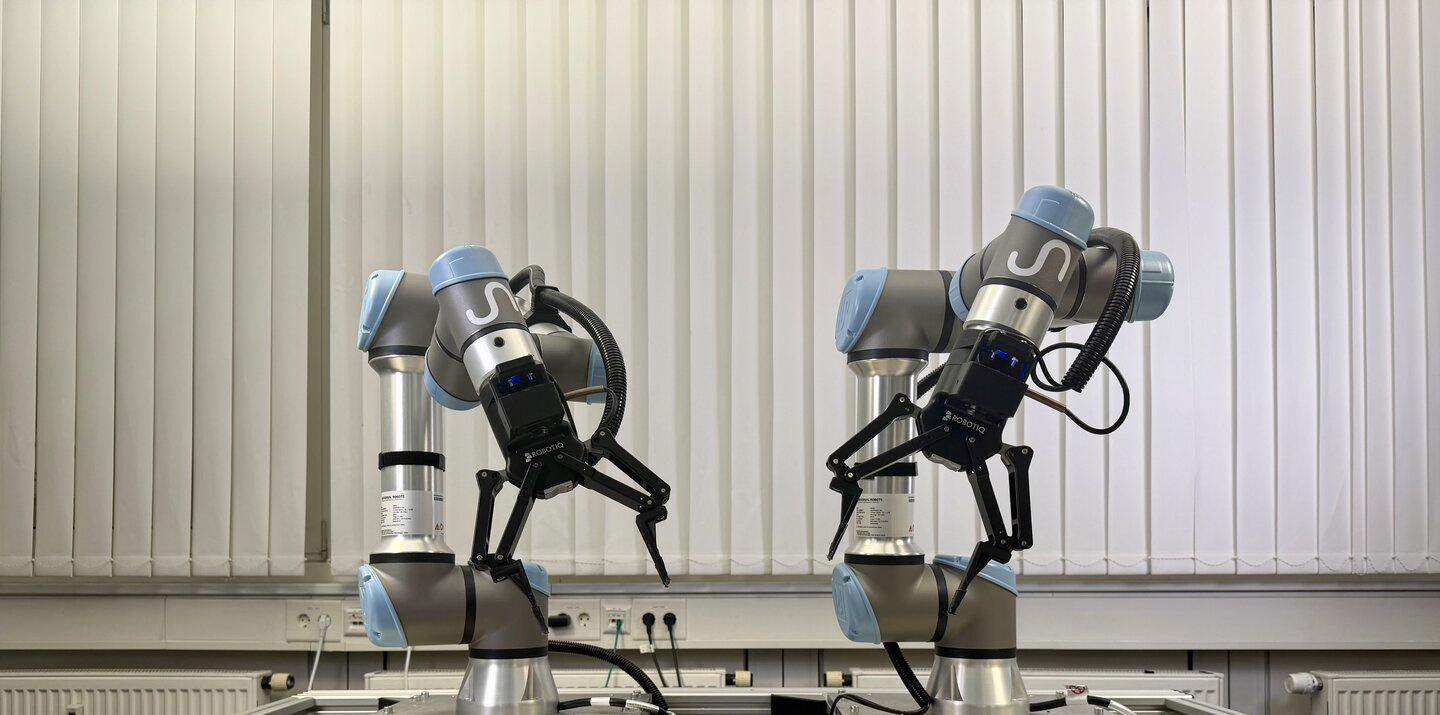
What it controlsArms and hands
Source and note: What it controlsA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Model card: “14 joint and gripper dimensions; absolute action targets”
Degrees of freedom controlled14DoF
Source and note: Degrees of freedom controlledA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Stationary Trossen ALOHA-style robot (“on a Stationary Trossen ALOHA-style robot.”): “14 joint and gripper dimensions; absolute action targets”.
Size and speed0/2 disclosed
ParametersNot stated
Source and note: ParametersA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. The model card lists vision-language backbone and action expert sizes separately (“`gemma_2b` / `gemma_300m`”) without a single combined total.
Control rateNot stated
Where it runs and what it is built on1/2 disclosed
On robot or cloudNot stated
Base modelπ₀.₅
Source and note: Base modelA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. Model card: “building on Physical Intelligence's π₀.₅”.
Openness2/3 disclosed
AccessOpen weights (download)
Source and note: AccessB arxiv.org/abs/2609.36416 · Retrieved 19 November 2026Note. Paper: “We open-source the full dataset, model weights, and training code.”
Licence documentGemma
Source and note: Licence documentA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. “The checkpoint retains the **Gemma license** inherited through its PaliGemma/π₀.₅ initialization.” “The LeRobot implementation is available under Apache 2.0”
Licence typeNot stated
Source and note: Licence typeA huggingface.co/lerobot/FineART-VLA-subtask-midtrained · Retrieved 19 November 2026Note. “The checkpoint retains the **Gemma license** inherited through its PaliGemma/π₀.₅ initialization.” “The LeRobot implementation is available under Apache 2.0”
The developer’s own claims2/2 disclosed
Learns new tasksWithout examples
Source and note: Learns new tasksB arxiv.org/abs/2609.36416 · Retrieved 19 November 2026Note. Developer claim: “Mid-training on FineART enables zero-shot transfer to unseen
tasks.”
Works across robotsYes
Source and note: Works across robotsB arxiv.org/abs/2609.36416 · Retrieved 19 November 2026Note. Developer claim: “the policy generalizes to unseen, multi-stage tasks
on a distinct robot platform (YAM)”.Yes only if the developer itself says the model runs on different robot models, for example robots from two manufacturers or two of one manufacturer’s models. Several units of the same robot do not count.
Notes
Scale AI and Hugging Face LeRobot describe the model: “We also introduce FineART-VLA, a vision-language- action policy that predicts its own next subtask to guide its actions.”
The authors open-source the dataset, model weights, and training code (“We open-source the full dataset, model weights, and training code.”).
Sources
One line per source, not per figure: a source has one retrieval date.
- Ahuggingface.co/lerobot/FineART-VLA-subtask-midtrainedMain source. Retrieved 19 November 2026
- Barxiv.org/abs/2609.36416Retrieved 19 November 2026
- Carxiv.org/abs/2609.36416v1Retrieved 19 November 2026