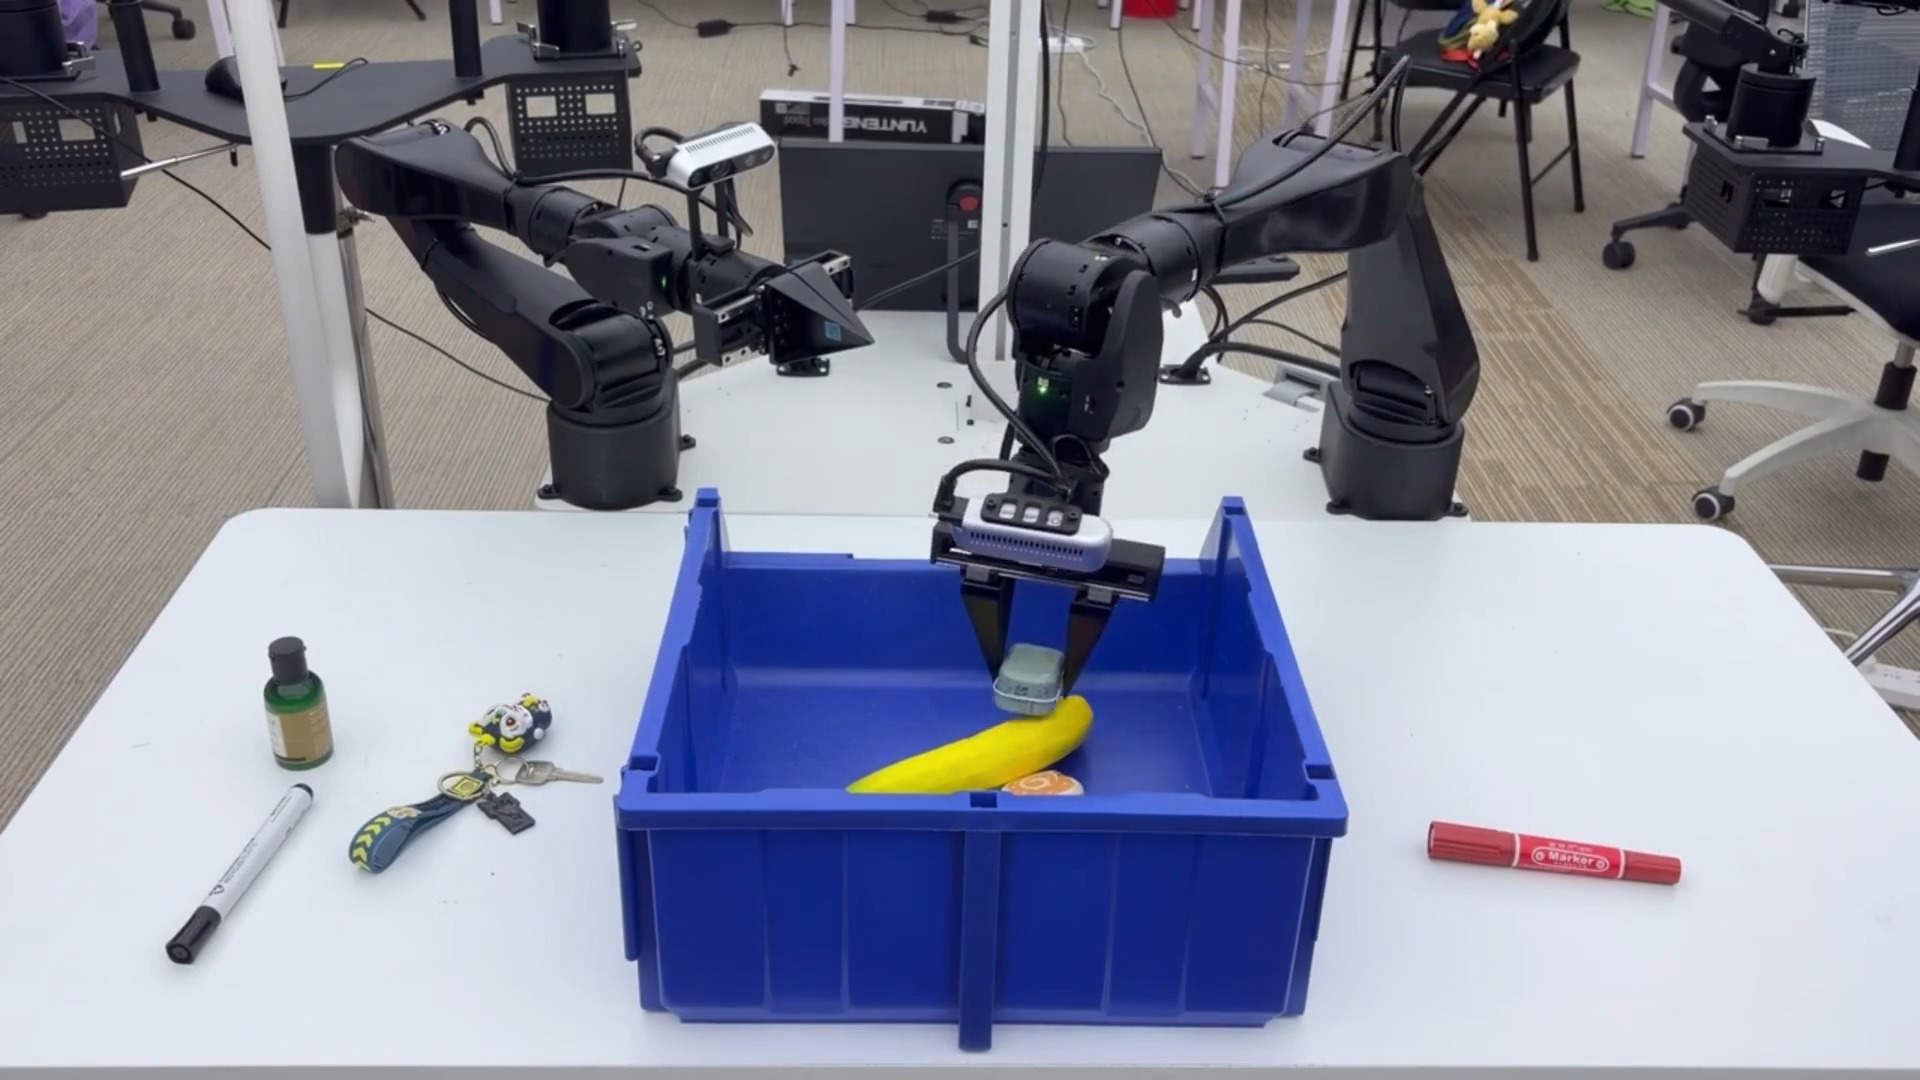
CUHK / StarVLA · robot AI model
VLAct
China · 2026
Sources retrieved: 19 November 2026 (A, B)
- Model type
- Vision-language-action (VLA)Source and note: Model typeB arxiv.org/abs/2608.27550 · Retrieved 19 November 2026Note. Paper abstract: “We propose VLAct, a VLA-oriented VLM backbone trained on broad, heterogeneous, multi-embodiment robot data before task-specific fine-tuning.”
- What it controls
- Arms and handsSource and note: What it controlsA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Pretraining mixture covers single-arm and dual-arm manipulation: “The VLA mixture combines heterogeneous AgileX/ALOHA and Franka data”.
- Inputs
- Camera Language Robot stateSource and note: InputsA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card describes a Vision-Language-Action backbone (“Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models”) where a downstream policy defines its “camera, state, action, normalization, and control contracts, then be fine-tuned for the target”.
- Access
- Open weights (download)Source and note: AccessA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Checkpoint download command: “hf download StarVLA/VLAct_Qwen3_Pretrain”
- Base model
- Qwen3-VL-4B-Instruct-ActionSource and note: Base modelA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card header: “base_model: StarVLA/Qwen3-VL-4B-Instruct-Action”
- Licence type
- Free, commercial useSource and note: Licence typeA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card header: “license: apache-2.0”
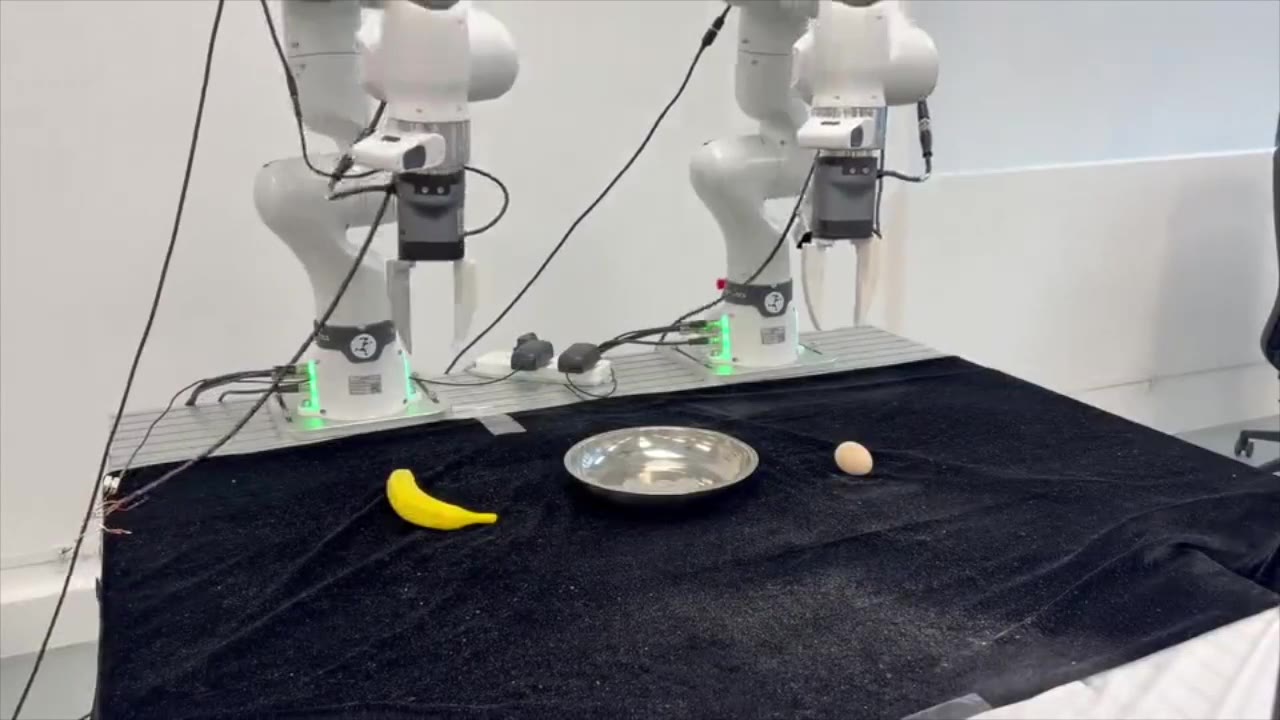
Specifications
10 of 14 stated 4 not stated
2 fields hidden 2 not-stated fields with a note stay ·
How to read the figuresShow guideClose
- not statedNo source
- yesStated by a source
- 0Reported as zero
- ASource
Select a source marker for source details and notes.
Release1/1 disclosed
Released27 August 2026
Source and note: ReleasedB arxiv.org/abs/2608.27550 · Retrieved 19 November 2026Note. arXiv submission date: “Submitted on 27 Aug 2026”
Input and output3/4 disclosed
Model typeVision-language-action (VLA)
Source and note: Model typeB arxiv.org/abs/2608.27550 · Retrieved 19 November 2026Note. Paper abstract: “We propose VLAct, a VLA-oriented VLM backbone trained on broad, heterogeneous, multi-embodiment robot data before task-specific fine-tuning.”
InputsCamera Language Robot state
Source and note: InputsA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card describes a Vision-Language-Action backbone (“Beyond Data Scaling: Representation-Centric Continued Pre-training for Vision-Language-Action Models”) where a downstream policy defines its “camera, state, action, normalization, and control contracts, then be fine-tuned for the target”.
What it controlsArms and hands
Source and note: What it controlsA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Pretraining mixture covers single-arm and dual-arm manipulation: “The VLA mixture combines heterogeneous AgileX/ALOHA and Franka data”.
Degrees of freedom controlledNot stated
Source and note: Degrees of freedom controlledA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Uses a unified padded representation: “20-D padded action / 14-D state”.
Size and speed0/2 disclosed
ParametersNot stated
Source and note: ParametersA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Built on “base_model: StarVLA/Qwen3-VL-4B-Instruct-Action” without a stated total parameter count for the pretraining checkpoint.
Control rateNot stated
Where it runs and what it is built on1/2 disclosed
On robot or cloudNot stated
Base modelQwen3-VL-4B-Instruct-Action
Source and note: Base modelA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card header: “base_model: StarVLA/Qwen3-VL-4B-Instruct-Action”
Openness3/3 disclosed
AccessOpen weights (download)
Source and note: AccessA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Checkpoint download command: “hf download StarVLA/VLAct_Qwen3_Pretrain”
Licence documentApache-2.0
Source and note: Licence documentA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Checkpoint weights: “license: apache-2.0”. “The VLAct code repository is released separately under the MIT License.”
Licence typeFree, commercial use
Source and note: Licence typeA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card header: “license: apache-2.0”
The developer’s own claims2/2 disclosed
Learns new tasksNeeds retraining
Source and note: Learns new tasksA huggingface.co/StarVLA/VLAct_Qwen3_Pretrain · Retrieved 19 November 2026Note. Model card: “camera, state, action, normalization, and control contracts, then be fine-tuned for the target”
Works across robotsYes
Source and note: Works across robotsB arxiv.org/abs/2608.27550 · Retrieved 19 November 2026Note. Developer claim: “We propose VLAct, a VLA-oriented VLM backbone trained on broad, heterogeneous, multi-embodiment robot data before task-specific fine-tuning.”Yes only if the developer itself says the model runs on different robot models, for example robots from two manufacturers or two of one manufacturer’s models. Several units of the same robot do not count.
Notes
Developers describe VLAct: “We propose VLAct, a VLA-oriented VLM backbone trained on broad, heterogeneous, multi-embodiment robot data before task-specific fine-tuning.”
Sources
One line per source, not per figure: a source has one retrieval date.
- Ahuggingface.co/StarVLA/VLAct_Qwen3_PretrainMain source. Retrieved 19 November 2026
- Barxiv.org/abs/2608.27550Retrieved 19 November 2026