Agibot · robot AI model
WITA-Omni
China · 2026
Sources retrieved: 30 October 2026 (A, B)
- Inputs
- Camera Language AudioSource and note: InputsA agibot.com/article/231/detail/86.html · Retrieved 30 October 2026Note. AGIBOT's announcement of the Preview: “It maps text, images, audio and audio-visual inputs into a shared representation space”.
Specifications
2/14 specifications disclosed 12 not stated
7 fields hidden 5 not-stated fields with a note stay ·
How to read the figuresShow guideClose
Not statedThe developer publishes nothing on it
Select a source marker for source details and notes.
Release1/1 disclosed
Released28 July 2026
Source and note: ReleasedA agibot.com/article/231/detail/86.html · Retrieved 30 October 2026Note. [A] AGIBOT's announcement of WITA-Omni Preview is dated “July 28, 2026”; the Innovation Day report is dated “October 29, 2026”.
Input and output1/4 disclosed
Model typeNot stated
Source and note: Model typeB agibot.com/article/231/detail/131.html · Retrieved 30 October 2026Note. AGIBOT's own term is not one of the listed types: “WITA Omni is the industry’s first robot-native end-to-end multimodal interaction model”; “an omni-modal foundation model that integrates visual perception, speech, real-time dialogue, facial expressions and physical actions into a continuous interaction system”.
InputsCamera Language Audio
Source and note: InputsA agibot.com/article/231/detail/86.html · Retrieved 30 October 2026Note. AGIBOT's announcement of the Preview: “It maps text, images, audio and audio-visual inputs into a shared representation space”.
What it controlsNot stated
Source and note: What it controlsA agibot.com/article/231/detail/86.html · Retrieved 30 October 2026Note. The model's movement output is not tied to arms, hands or the whole body: “Actor uses dedicated motion and facial-expression heads to generate physical movements and expressions alongside speech”.
Degrees of freedom controlledNot stated
Size and speed0/2 disclosed
ParametersNot stated
Control rateNot stated
Where it runs and what it is built on0/2 disclosed
On robot or cloudNot stated
Source and note: On robot or cloudB agibot.com/article/231/detail/131.html · Retrieved 30 October 2026Note. AGIBOT says only: “The model supports full-duplex conversation, coordinated speech and movement, and on-device deployment”.
Base modelNot stated
Openness0/3 disclosed
AccessNot stated
Source and note: AccessB agibot.com/article/231/detail/131.html · Retrieved 30 October 2026Note. AGIBOT gives no download or API; its Innovation Day report says it “presents WITA-Omni and its planned deployment roadmap for more natural, multimodal human–robot interaction”.
Licence documentNot stated
Licence typeNot stated
The developer’s own claims0/2 disclosed
Learns new tasksNot stated
Works across robotsNot stated
Source and note: Works across robotsYes only if the developer itself says the model runs on different robot models, for example robots from two manufacturers or two of one manufacturer’s models. Several units of the same robot do not count.
Notes
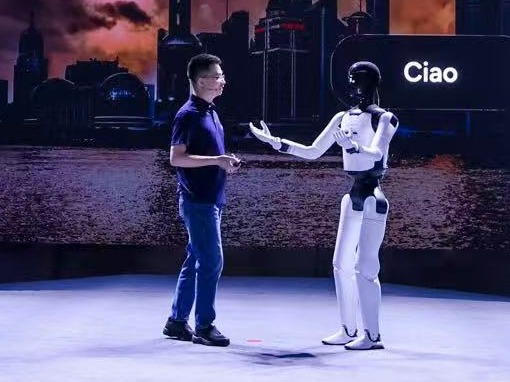
AGIBOT announced WITA-Omni Preview on 28 July 2026 and showed WITA-Omni at its Innovation Day on 29 October 2026.
AGIBOT describes WITA-Omni as a Thinker-Talker-Actor model that produces speech, movement and facial expression.
Sources
One line per source, not per figure: a source has one retrieval date.
- Aagibot.com/article/231/detail/86.htmlMain source. Retrieved 30 October 2026
- Bagibot.com/article/231/detail/131.htmlRetrieved 30 October 2026